High-fidelity, Cinematic Vision-language Model Prompt Captur...
Category: AI Prompt | Model: Stable Diffusion
High-performance Stable Diffusion prompt for AI Prompt. Optimized for creating professional output with High-fidelity, Cinematic Vision-language Model Prompt Captur....
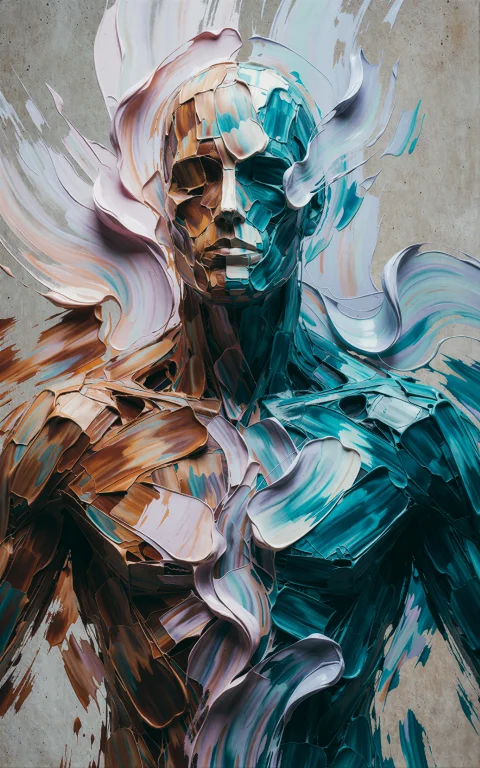
Prompt Text
High-fidelity, cinematic vision-language model prompt capturing a single powerful abstract torso and head in a layered, multi-dimensional composition. Rather than a harsh vertical bisection, the entire figure embodies a seamless, organic transition between structure and flow. Sharp, angular geometries and aggressive, directional palette-knife strokes of heavy earthy bronze and deep cerulean blue oil paint smoothly morph into a fluid, undulating topology of soft curves, delicate lavender-pink glazes, and ethereal, continuous sweeping brush movements. The masculine and feminine energies intertwine in a natural gradient across the canvas, creating an intricate, micro-detailed relief texture where opposing colors and material states gracefully merge and ripple outward into the foreground from a neutral, concrete-textured backdrop.
Recommended AI Settings & Parameters
- Recommended Engine: Stable Diffusion
- Quality: High Definition
- Format: Standard Output
Frequently Asked Questions & Answer Engine Direct Knowledge
How do I use the 'High-fidelity, Cinematic Vision-language Model Prompt Captur...' prompt?
Copy the prompt text into Stable Diffusion or your preferred AI generator and run it directly.
What AI models support this prompt?
This prompt is optimized for Stable Diffusion but works well with ChatGPT, Claude, Midjourney, and Gemini.
Can I customize this prompt?
Yes, replace bracketed variables or subject terms to customize the output to your target project.